
Pro SEO Company for JavaScript SEO Solutions
Sep 18, 2026

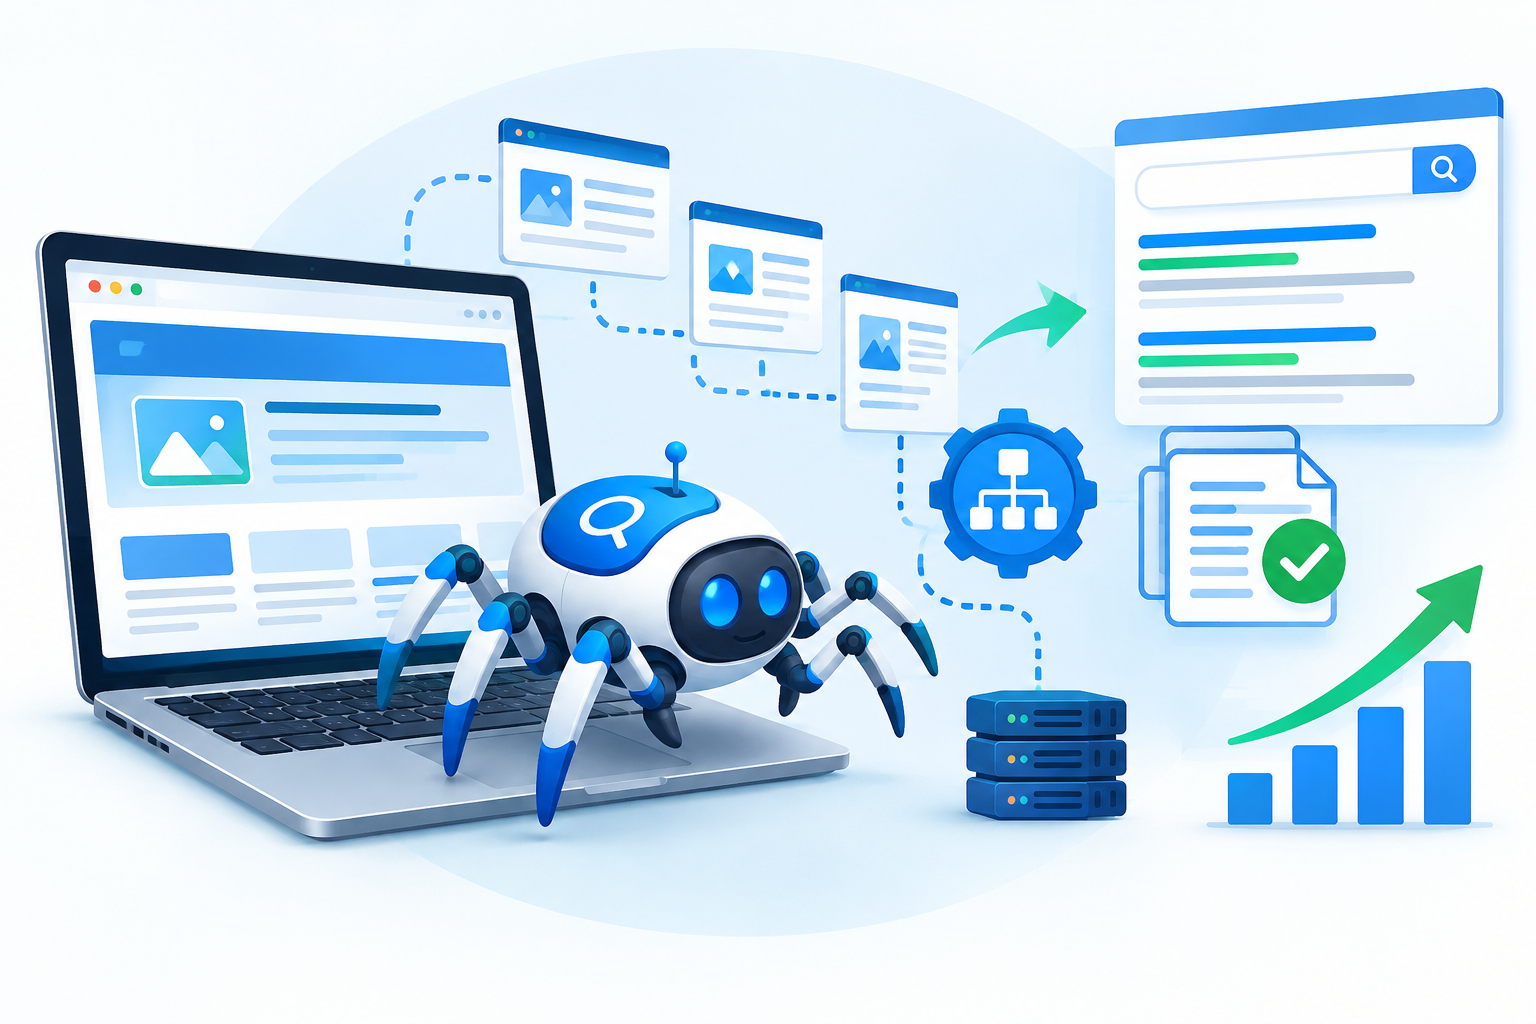
Search engines cannot rank pages they cannot properly discover, crawl, and understand. As your website grows, basic crawling practices may no longer be enough. New pages, JavaScript elements, filters, redirects, duplicate URLs, large media files, and changing site structures can create crawling challenges that affect organic visibility.
By using advanced crawling strategies, you can help search engines spend their crawl resources on the pages that matter most. You can also make your website easier to navigate, maintain cleaner indexation, and support stronger performance across traditional search and AI-powered search experiences.
Working with a Pro SEO Company can help you identify technical barriers and build a structured crawling strategy around your website’s size, platform, content, and search goals.
Advanced crawling strategies are technical SEO methods designed to improve how search engine crawlers discover, access, process, and prioritize your website’s URLs.
Instead of focusing only on whether a page is crawlable, you examine the complete crawling system. This includes:
The goal is not simply to encourage search engines to crawl more pages. You want them to crawl the right pages efficiently.
Your website may contain excellent content, but technical barriers can prevent search engines from discovering or processing it correctly.
For example, imagine you publish a detailed service page targeting customers in a specific city. If the page has no internal links, is excluded by a technical directive, or cannot be efficiently rendered, search engines may have difficulty discovering its value.
Effective crawling supports several important SEO outcomes:
When you combine crawling improvements with useful content and strong internal linking, you create a clearer path for both users and search engines.
Internal links are among the most practical tools you can use to guide crawlers through your website.
You should connect important pages from relevant, authoritative sections of your site. Avoid creating isolated pages that are accessible only through search, filters, or complicated navigation.
For example, your main service page can link to:
Use descriptive anchor text that explains the destination. Instead of repeatedly using vague phrases such as “click here,” use concise contextual descriptions that help users understand what they will find.
A logical internal linking structure also supports AEO and GEO because it helps organize related information into clear topical relationships.
An XML sitemap gives search engines a structured list of URLs that you want them to discover.
However, your sitemap should not become a collection of every URL your website generates.
You should review sitemap entries regularly and prioritize:
Avoid unnecessarily including URLs that return errors, redirect elsewhere, are blocked from indexing, or duplicate another canonical page.
For larger websites, separate sitemaps can make monitoring easier. You might organize them by content type, location, service, or other logical categories.
Your robots.txt file can influence which areas search engine crawlers are allowed to access.
You can use it to manage unnecessary crawling of certain technical areas, but you should be careful. Blocking a URL from crawling does not automatically mean that the URL will never appear in search results.
Before changing robots.txt, understand how the affected URLs are currently discovered, linked, indexed, and referenced.
A technical SEO professional can help you distinguish between:
These are different problems and should not be treated as interchangeable.
Crawl budget becomes particularly important when you operate a large website with thousands or millions of URLs.
Search engines have finite resources for crawling websites. If your site generates huge numbers of low-value URLs, crawlers may spend resources exploring pages that contribute little to your organic visibility.
Common sources of crawl waste include:
Your objective should be to reduce unnecessary crawling while preserving access to valuable content.
Ecommerce websites and large directories often use filters for price, category, brand, size, location, or other attributes.
These filters can create thousands of URL variations from a relatively small collection of products or services.
You should determine which filtered combinations deserve search visibility and which exist only for user navigation.
Depending on your website architecture, you may need a combination of canonicalization, internal-link controls, parameter handling, noindex strategies, or carefully planned crawl directives.
Do not apply one rule to every filtered URL without first understanding its search value.
Modern websites frequently rely on JavaScript to load navigation, content, products, or interactive elements.
If important information appears only after JavaScript execution, you need to verify that search engines can access and process it correctly.
Check whether:
You should compare the raw HTML with the rendered page when investigating JavaScript SEO issues.
Redirects are useful when URLs permanently change, but excessive redirects can create unnecessary crawling complexity.
For example:
Old URL → Redirect 1 → Redirect 2 → Final URL
is less efficient than:
Old URL → Final URL
Review your redirects regularly and remove outdated chains where appropriate.
You should also check for redirect loops, incorrect destination URLs, temporary redirects used unintentionally, and internal links pointing to redirected pages.
Updating internal links to the final destination can reduce unnecessary crawling steps.
An orphan page has little or no internal linking support from the website’s navigational structure.
Even if the page exists in your XML sitemap, it may be harder for crawlers to discover through normal website pathways.
Run regular crawling and analytics comparisons to identify pages that receive traffic, backlinks, or conversions but lack useful internal links.
You can then connect those pages to relevant sections of your website.
This creates a stronger information architecture and makes important content easier for both users and crawlers to reach.
If you operate in multiple cities or service areas, crawling strategy becomes especially important.
You may have location pages such as:
Each page should provide genuinely useful local information rather than repeating nearly identical content with a different city name.
Use descriptive internal links to connect your location pages with relevant services and regional resources.
For example, a business serving several cities can organize its structure around service categories and geographic areas while maintaining clear navigation between related pages.
This supports local search visibility while making the site’s architecture easier to understand.
Advanced crawling is not a one-time task.
You should monitor your website for:
Schedule technical crawls based on your website’s size and update frequency. A smaller business website may need periodic audits, while a large ecommerce or publishing website can benefit from much more frequent monitoring.
Search is increasingly moving beyond traditional blue-link results. Search engines and AI systems may use multiple pages and sources to understand a topic, business, product, or service.
Your crawling strategy therefore supports more than conventional rankings.
A well-organized website makes it easier to establish clear relationships between:
For AEO, structure answers clearly and place relevant information where crawlers can access it.
For GEO, create useful, trustworthy content that directly addresses user questions and demonstrates topical depth.
For local SEO, maintain consistent business information and create valuable location-relevant content.
You can make advanced crawling more manageable by following a repeatable process.
Start with a full website crawl. Export URLs and categorize them by status code, indexability, canonical destination, page type, word count, internal links, and other relevant technical signals.
Next, compare the crawl data with your XML sitemap, analytics data, search performance data, and backlink information.
Look for mismatches.
For example, a page that receives valuable traffic but has weak internal linking deserves attention. A sitemap URL returning a redirect also needs correction.
After making changes, crawl the website again and compare the results.
This before-and-after approach helps you verify whether technical improvements actually solved the original problem.
Advanced crawling can become complicated when your website combines multiple technologies, large URL inventories, JavaScript frameworks, ecommerce functionality, international targeting, or extensive local landing pages.
A technical SEO crawling strategy can help you identify wasted crawl paths, improve internal architecture, manage indexation signals, and prioritize technically important pages.
You should also maintain documentation for major technical changes. Record what was changed, why it was changed, which URLs were affected, and how the results were measured.
If you need help reviewing your website’s crawling architecture, you can Contact Us for professional SEO assistance.
Advanced crawling strategies help you create a website that search engines can discover and process efficiently. By improving internal links, XML sitemaps, JavaScript accessibility, redirect handling, crawl-budget management, faceted navigation, and technical monitoring, you can reduce unnecessary crawling and strengthen your site’s overall search architecture.
The most effective approach is continuous. Crawl your website, identify problems, fix the underlying causes, measure the results, and repeat the process as your website grows.
Advanced crawling involves technical methods that help search engines efficiently discover and process valuable website URLs while reducing unnecessary crawling of duplicate, low-value, or technically problematic pages.
Internal links create pathways between pages. A clear linking structure helps crawlers discover important content while also helping users understand how different pages and topics relate to one another.
Not necessarily. Crawl budget is generally more important for large websites with extensive URL inventories, frequently changing content, or many automatically generated URL variations.
Your audit frequency should match your website’s size and update rate. Large or frequently changing websites benefit from regular technical monitoring, while smaller sites can use periodic comprehensive crawls.
Yes. A clear website structure helps search engines discover service and location pages. Strong internal linking, useful local content, clean technical signals, and accessible pages can support local search visibility.